Made with these models
The 5 models this integration runs.
eleven_flash_v2_5 on elevenlabs
eleven_flash_v2_5text-to-speech
eleven_multilingual_v2 on elevenlabs
eleven_multilingual_v2text-to-speech
eleven_turbo_v2_5 on elevenlabs
eleven_turbo_v2_5text-to-speech
eleven_v3 on elevenlabs
eleven_v3text-to-speech
Sound effects
sound-effectstext-to-speech
eleven_flash_v2_5 on elevenlabs
eleven_flash_v2_5text-to-speech
eleven_multilingual_v2 on elevenlabs
eleven_multilingual_v2text-to-speech
eleven_turbo_v2_5 on elevenlabs
eleven_turbo_v2_5text-to-speech
eleven_v3 on elevenlabs
eleven_v3text-to-speech
Sound effects
sound-effectstext-to-speech
Turn any text in your pipeline into natural speech, in 30+ languages.
- 30+ languages, selectable voice per node
- Takes text from anywhere in the graph
- Audio stored in your library with normal retention
- Flash models cost half the multilingual rate
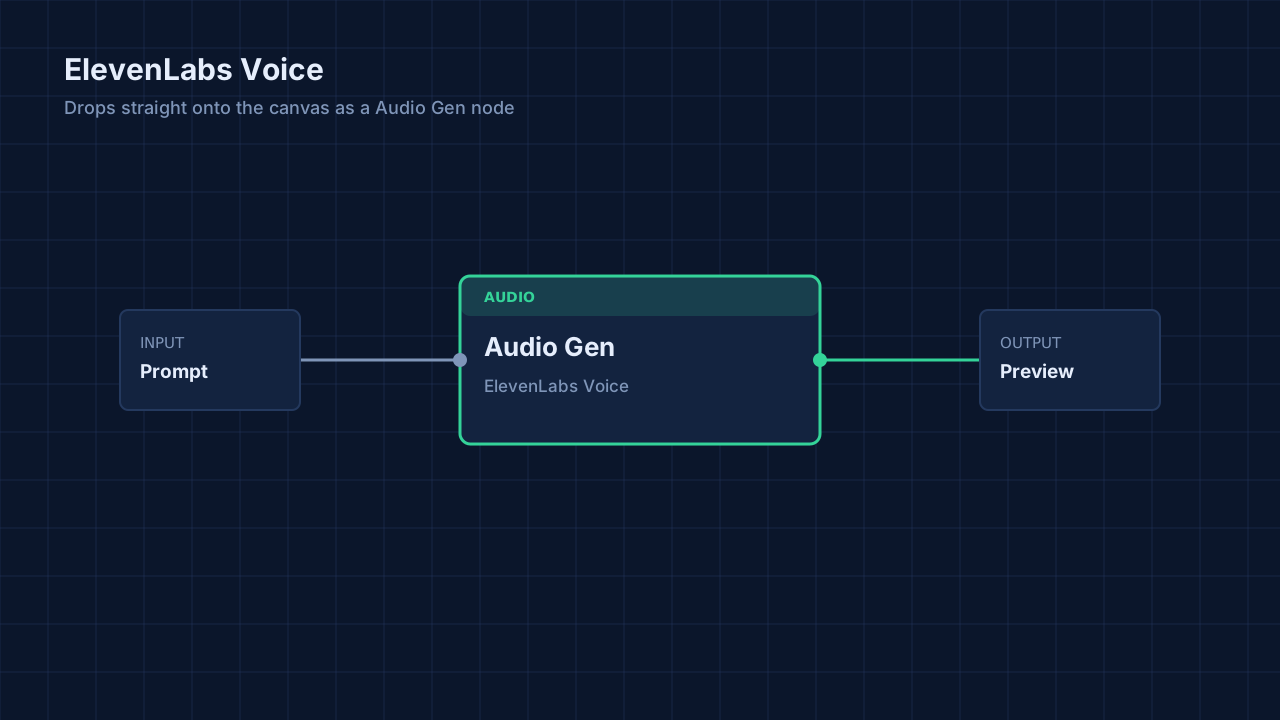
Give a pipeline a voice. The Audio Gen node sends any upstream text to ElevenLabs and returns speech — narration for a generated scene, a line of character dialogue written by an LLM Worker, or a spoken summary of a document.
Because it takes text from anywhere in the graph, it composes: Claude writes the script, ElevenLabs performs it, and a delivery node ships the audio. Voice, model, stability and similarity are inspector fields.
Audio is written straight into your own Sushibelt storage and registered in your library with the same retention as every other output. Charged per character of input text, at ElevenLabs' published rate — the faster flash models cost half what multilingual does.
audiotext-to-speechvoicenarrationelevenlabstts