Made with these models
The 9 models this integration runs.
gpt-5.4 on openai
gpt-5.4text-to-text
gpt-5.4-mini on openai
gpt-5.4-minitext-to-text
gpt-5.4-nano on openai
gpt-5.4-nanotext-to-text
gpt-5.4-pro on openai
gpt-5.4-protext-to-text
gpt-5.5 on openai
gpt-5.5text-to-text
gpt-5.5-pro on openai
gpt-5.5-protext-to-text
gpt-5.6-luna on openai
gpt-5.6-lunatext-to-text
gpt-5.6-sol on openai
gpt-5.6-soltext-to-text
gpt-5.6-terra on openai
gpt-5.6-terratext-to-text
GPT-4o and GPT-4-turbo for advanced language tasks.
- GPT-5.x family selectable per node
- Input and output tokens charged at their real split rates
- Run alongside another provider to compare in one graph
- Bring your own OpenAI key, or run on the platform key
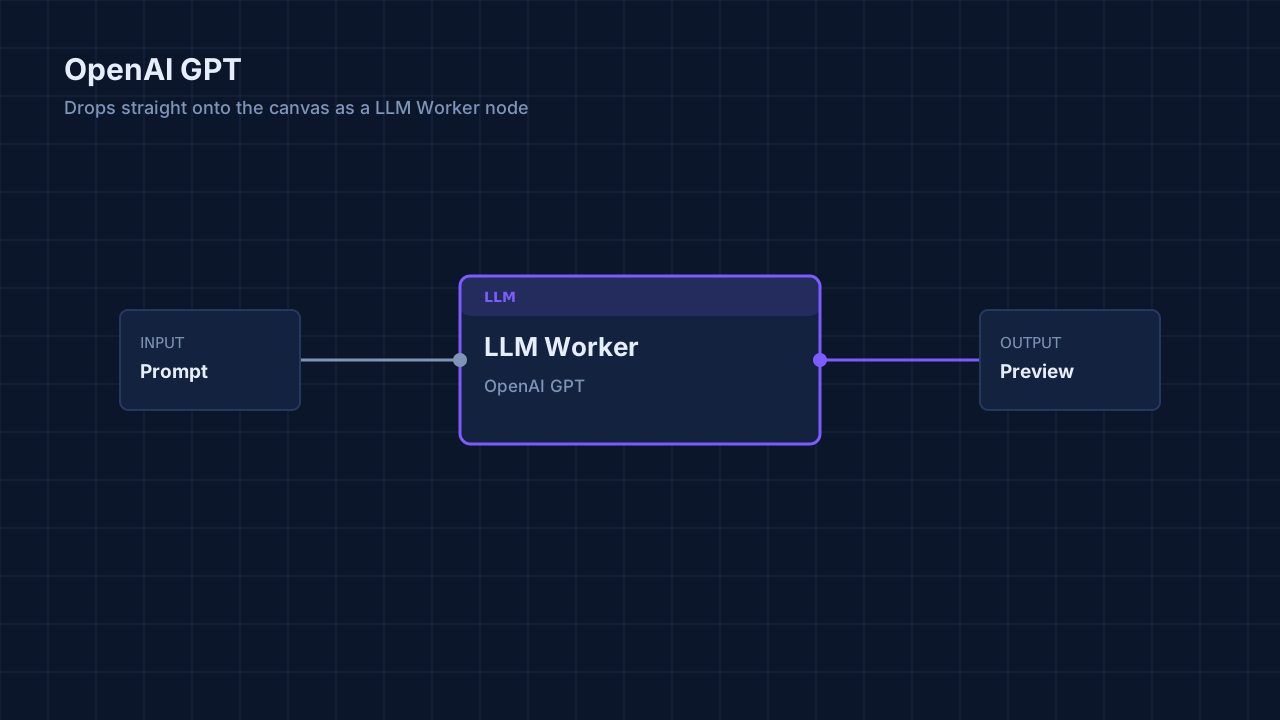
The GPT family as an LLM Worker node. Same role as Claude in a pipeline — planning, rewriting, extraction, classification, routing — with OpenAI's models behind it, so you can pick per node rather than per platform.
Useful when you want a second opinion in the same graph: run two LLM Workers on different providers, feed both into a Json Extractor, and compare. Cross-model orchestration in one canvas is the point.
Input and output tokens are priced separately by OpenAI (output costs several times more), and Sushibelt charges on the real split reported by the API rather than a blended guess. Bring your own OpenAI key per project, or use the platform key.
llmreasoningtextgptopenaistructured-output