Made with these models
The 7 models this integration runs.
Music from genre tags (ACE-Step)
ace-steptext-to-speech
Expressive speech (Chatterbox)
chatterboxtext-to-speech
Cheap voice lines, 26 voices (Kokoro)
kokoro-82mtext-to-speech
musicgen on replicate
musicgentext-to-speech
Voice lines, nine speakers (Qwen3-TTS)
qwen3-ttstext-to-speech
Sound effects from a prompt
stable-audiotext-to-speech
Sound effects and music (Stable Audio 2.5)
stable-audio-2.5text-to-speech
Generate instrumental music and sound beds from a text prompt.
- Instrumental music from a plain text prompt
- Up to 30 seconds per run
- Complements ElevenLabs — score as well as speech
- Billed by real GPU seconds, reported by Replicate
- Bring your own key, or run on the platform key
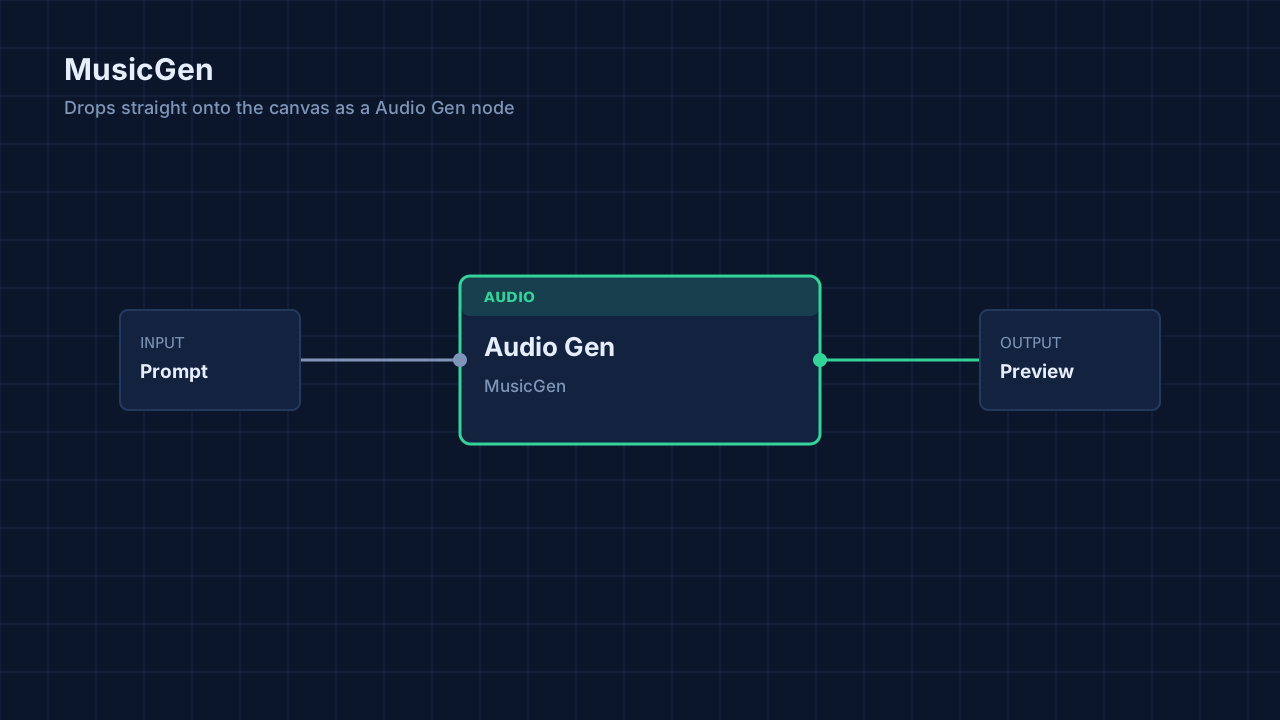
MusicGen writes instrumental music from a text description — a loop for a level, a sound bed under a generated video, ambient texture for a scene. It complements ElevenLabs rather than competing with it: ElevenLabs speaks, MusicGen scores.
Because the prompt can come from anywhere in the graph, an LLM Worker can write the musical description from the same brief that drove the art, which keeps a generated scene coherent across modalities.
Duration is capped at 30 seconds per run. Billed by GPU runtime on Replicate's A100 tier, so a short clip genuinely costs less.
audiomusicmusicgengenerationsoundtrackreplicate